 arXiv
UR5
Base Cartesian Policy
EmbodiSteer
Steering Embodiment-Agnostic Visuomotor Policies with Joint-Space Guidance for Zero-Shot Cross-Embodiment Deployment
Tsinghua University | Beijing Key Laboratory of Embodied Intelligence Systems | BNRist
*Equal contribution. †Corresponding authors.
CoRL 2026 Spotlight✨
Overview Video
Sound on
Abstract
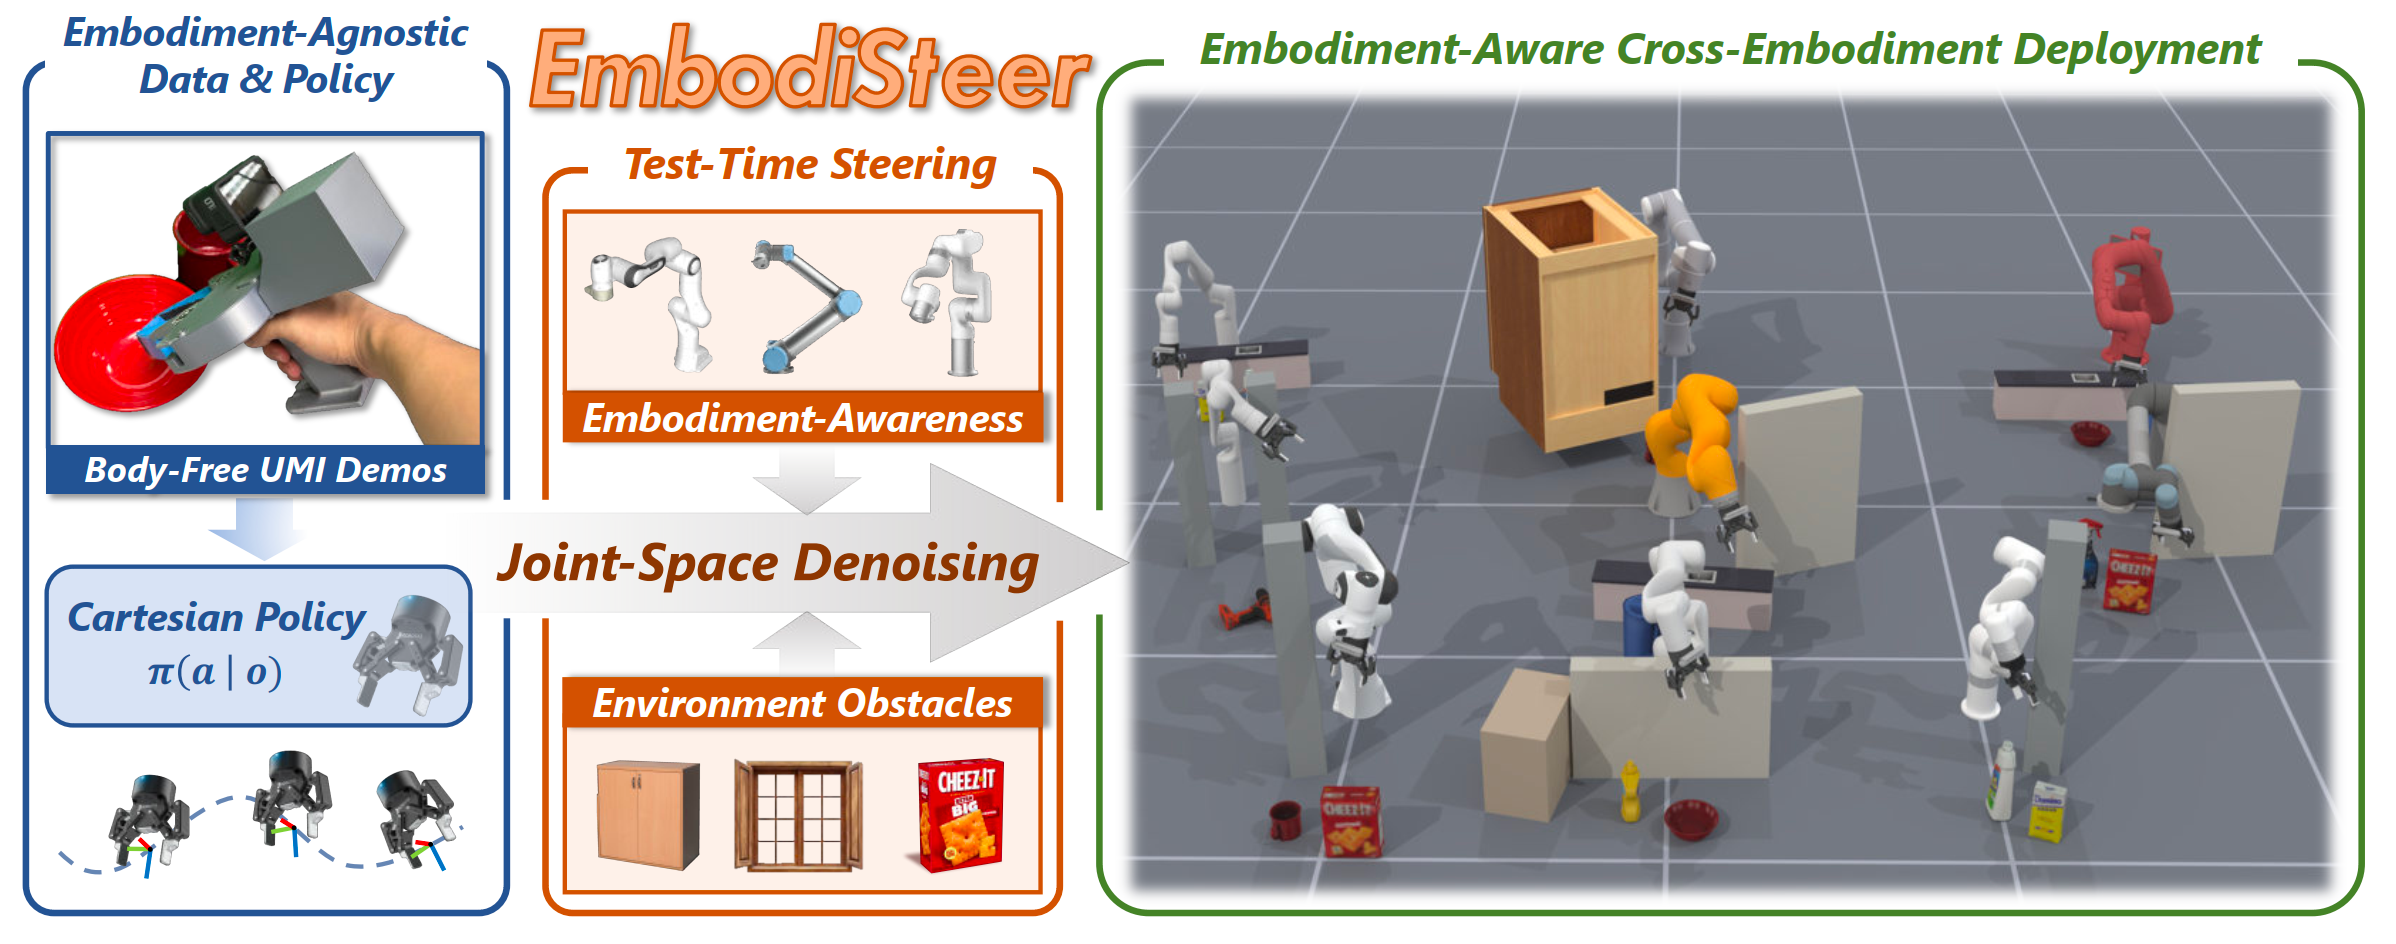
Scalable robot imitation learning relies on large-scale heterogeneous data from diverse robots or body-free data, making Cartesian end-effector actions a key interface for embodiment-agnostic policy learning. However, end-effector-only abstraction leaves Cartesian policies unaware of the deployed robot body, making them brittle under robot-specific constraints such as whole-body collision avoidance. To overcome this limitation, we present EmbodiSteer, a training-free framework that steers embodiment-agnostic visuomotor policies toward zero-shot, embodiment-aware deployment. EmbodiSteer keeps policy learning in Cartesian space while efficiently lifting inference-time diffusion sampling into the target robot's joint space via forward kinematics and Jacobian-based updates. With whole-body collision-aware guidance over joint trajectories after each denoising step, the arm can be steered away from collisions while preserving learned end-effector behavior. Across 9 simulated robots, EmbodiSteer reduces collision rate by 46.1 percentage points and increases task success by 28.5 percentage points over Cartesian-only execution; on two physical robots in highly constrained scenarios, the respective improvements are 90.0 and 36.7 percentage points.
+28.5 pp
simulation success rate
-46.1 pp
simulation collision rate
+36.7 pp
real-world success rate
-90.0 pp
real-world collision rate
All improvements are absolute changes in percentage points (pp), relative to Cartesian-only execution.
Real-World Results
Same UMI-trained checkpoint, zero-shot deployment on two robot embodiments
Compare Base Cartesian Policy and EmbodiSteer rollouts on UR5 and Franka Panda. Each task shares one checkpoint, trained on 200 obstacle-free UMI demonstrations, across the two robots. Obstacles are introduced only at deployment.
All rollouts are shown at 2x speed.
Make Iced Coffee
Obstacle layout
UR5
EmbodiSteer
Franka Panda
Base Cartesian Policy
Franka Panda
EmbodiSteer
Put Flower in Vase
Obstacle layout
UR5
Base Cartesian Policy
UR5
EmbodiSteer
Franka Panda
Base Cartesian Policy
Franka Panda
EmbodiSteer
Arrange Banana
Obstacle layout
UR5
Base Cartesian Policy
UR5
EmbodiSteer
Franka Panda
Base Cartesian Policy
Franka Panda
EmbodiSteer
Real-world results by robot and task
TSR and COR are success and collision counts over 10 trials per robot-task pair. Task success and obstacle contact are evaluated independently. The total aggregates 60 trials, as in Table 12 of the paper.
| Robot | Task | No Obstacles, Base Policy | Obstacles, Base Policy | Obstacles, EmbodiSteer | ||
|---|---|---|---|---|---|---|
| TSR ↑ | TSR ↑ | COR ↓ | TSR ↑ | COR ↓ | ||
| UR5 | Make Iced Coffee | 9/10 | 4/10 | 10/10 | 8/10 | 1/10 |
| Put Flower in Vase | 7/10 | 4/10 | 9/10 | 6/10 | 1/10 | |
| Arrange Banana | 8/10 | 4/10 | 9/10 | 9/10 | 0/10 | |
| Franka Panda | Make Iced Coffee | 9/10 | 6/10 | 10/10 | 8/10 | 1/10 |
| Put Flower in Vase | 6/10 | 1/10 | 10/10 | 6/10 | 0/10 | |
| Arrange Banana | 10/10 | 6/10 | 10/10 | 10/10 | 1/10 | |
| Total | All tasks | 49/60 | 25/60 | 58/60 | 47/60 | 4/60 |
Simulation Results
Evaluation across 9 robot embodiments
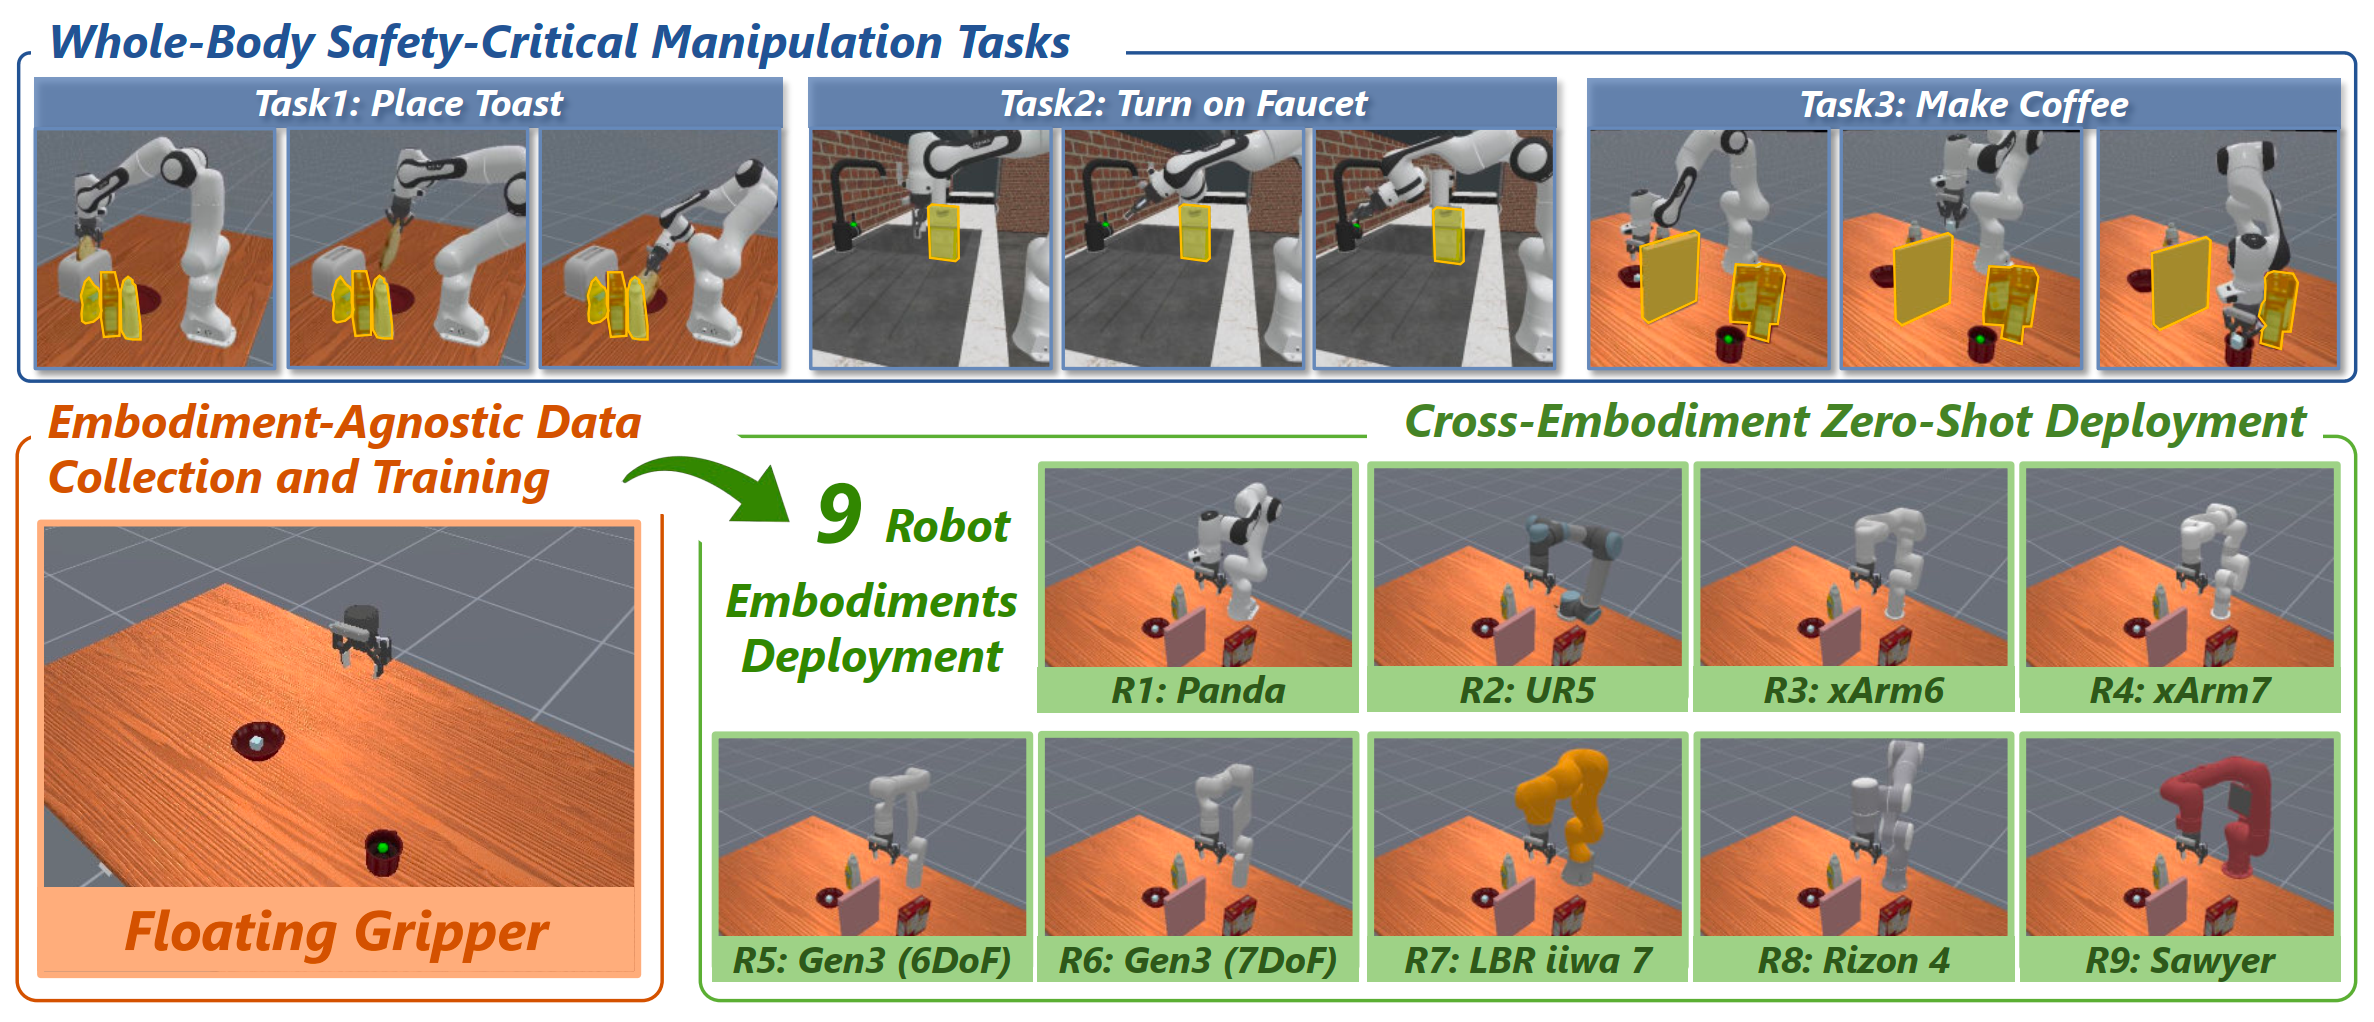
Quantitative results in simulation across 9 robot embodiments
TSR is task success rate (%), RWD is maximum reward per episode, and COR is collision occurrence rate (%). Values are averaged over nine robot embodiments, as in Table 1 of the paper.
| Obstacles | Method | PlaceToast | TurnOnFaucet | MakeCoffee | Average | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| TSR ↑ | RWD ↑ | COR ↓ | TSR ↑ | RWD ↑ | COR ↓ | TSR ↑ | RWD ↑ | COR ↓ | TSR ↑ | RWD ↑ | COR ↓ | ||
| w/o Obs. | EE | 96.8 | .980 | -- | 83.6 | .937 | -- | 89.7 | .932 | -- | 90.0 | .950 | -- |
| Joint | 94.4 | .965 | -- | 87.9 | .957 | -- | 89.7 | .929 | -- | 90.7 | .950 | -- | |
| w/ Obs. | EE | 43.4 | .634 | 52.6 | 41.6 | .752 | 61.8 | 22.2 | .456 | 58.3 | 35.7 | .614 | 57.6 |
| EE w/ Sampling | 47.1 | .661 | 51.3 | 43.9 | .767 | 53.2 | 24.1 | .478 | 60.0 | 38.4 | .635 | 54.8 | |
| EE w/ CBF | 65.8 | .764 | 15.3 | 56.3 | .797 | 29.9 | 48.9 | .606 | 8.6 | 57.0 | .722 | 17.9 | |
| Joint w/ CG | 57.7 | .687 | 0.2 | 10.3 | .403 | 59.6 | 22.4 | .424 | 40.6 | 30.1 | .505 | 33.5 | |
| EmbodiSteer | 74.8 | .829 | 4.6 | 60.6 | .833 | 27.1 | 57.2 | .670 | 2.8 | 64.2 | .777 | 11.5 | |
Simulation results across three evaluation seeds
Mean ± standard deviation across three seeds, averaged over the three tasks and nine robot embodiments under obstacles, as in Table 2 of the paper.
| Method | TSR (%) ↑ | RWD ↑ | COR (%) ↓ |
|---|---|---|---|
| EE | 36.0 ± 0.2 | .614 ± .004 | 56.8 ± 0.9 |
| EE w/ Sampling | 37.7 ± 0.5 | .621 ± .012 | 53.1 ± 1.3 |
| EE w/ CBF | 57.2 ± 0.6 | .726 ± .005 | 18.3 ± 0.3 |
| Joint w/ CG | 30.3 ± 0.5 | .503 ± .003 | 33.5 ± 0.6 |
| EmbodiSteer | 63.3 ± 1.4 | .771 ± .011 | 11.7 ± 0.8 |
Demonstration coverage
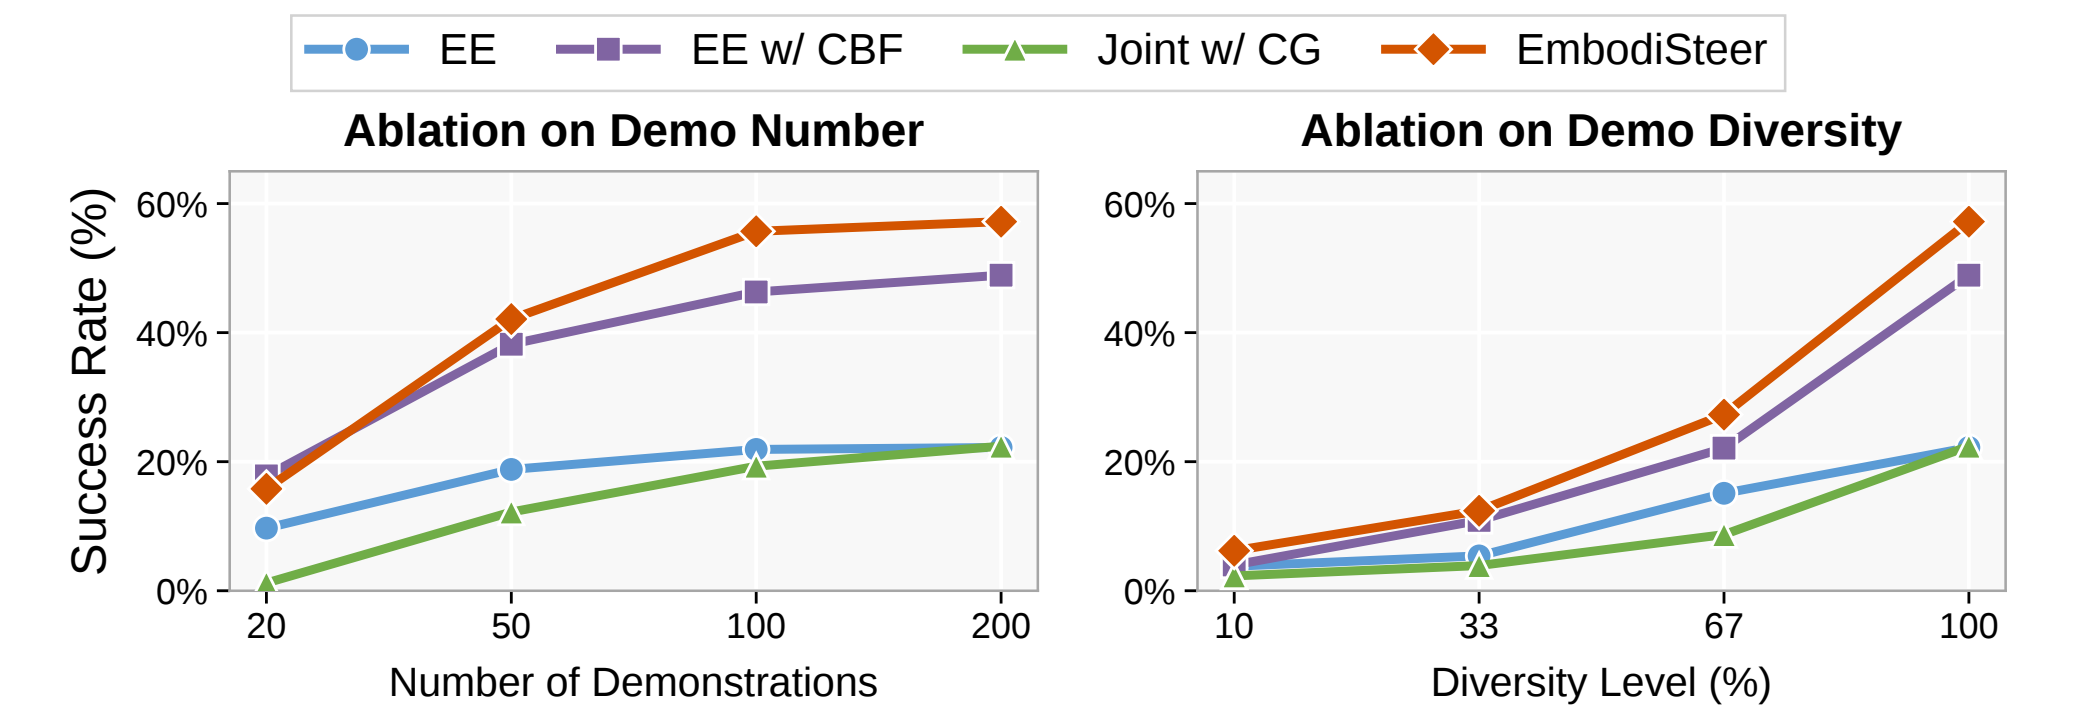
Collision guidance perturbs policy-proposed motion, making the coverage of training demonstrations relevant to task performance. On MakeCoffee, we vary the number of demonstrations (20, 50, 100, or 200) and, separately, trajectory diversity. Diversity scales the waypoint randomization used during motion-planning data generation to 10%, 33%, 67%, or 100% of the original setting, with 200 demonstrations at each level. Increasing either quantity or diversity improves task success under guidance.
Alternative constraint integration
We also implement a JM2D-style baseline that combines the same frozen Cartesian policy with whole-body constraints through repeated candidate denoising. On PlaceToast with Panda, under the same RTX 4090, batch-1, CUDA-synchronized conditions, this adaptation takes 8.65 s per chunk with 16 proposals and 16 denoising steps, versus 0.254 s for EmbodiSteer. Reducing JM2D to four steps still takes 3.27 s per chunk. This cost limits its practicality for closed-loop replanning in our setting, so the paper reports computational feasibility rather than a full task-performance comparison.
Method
Lift Cartesian denoising into joint space
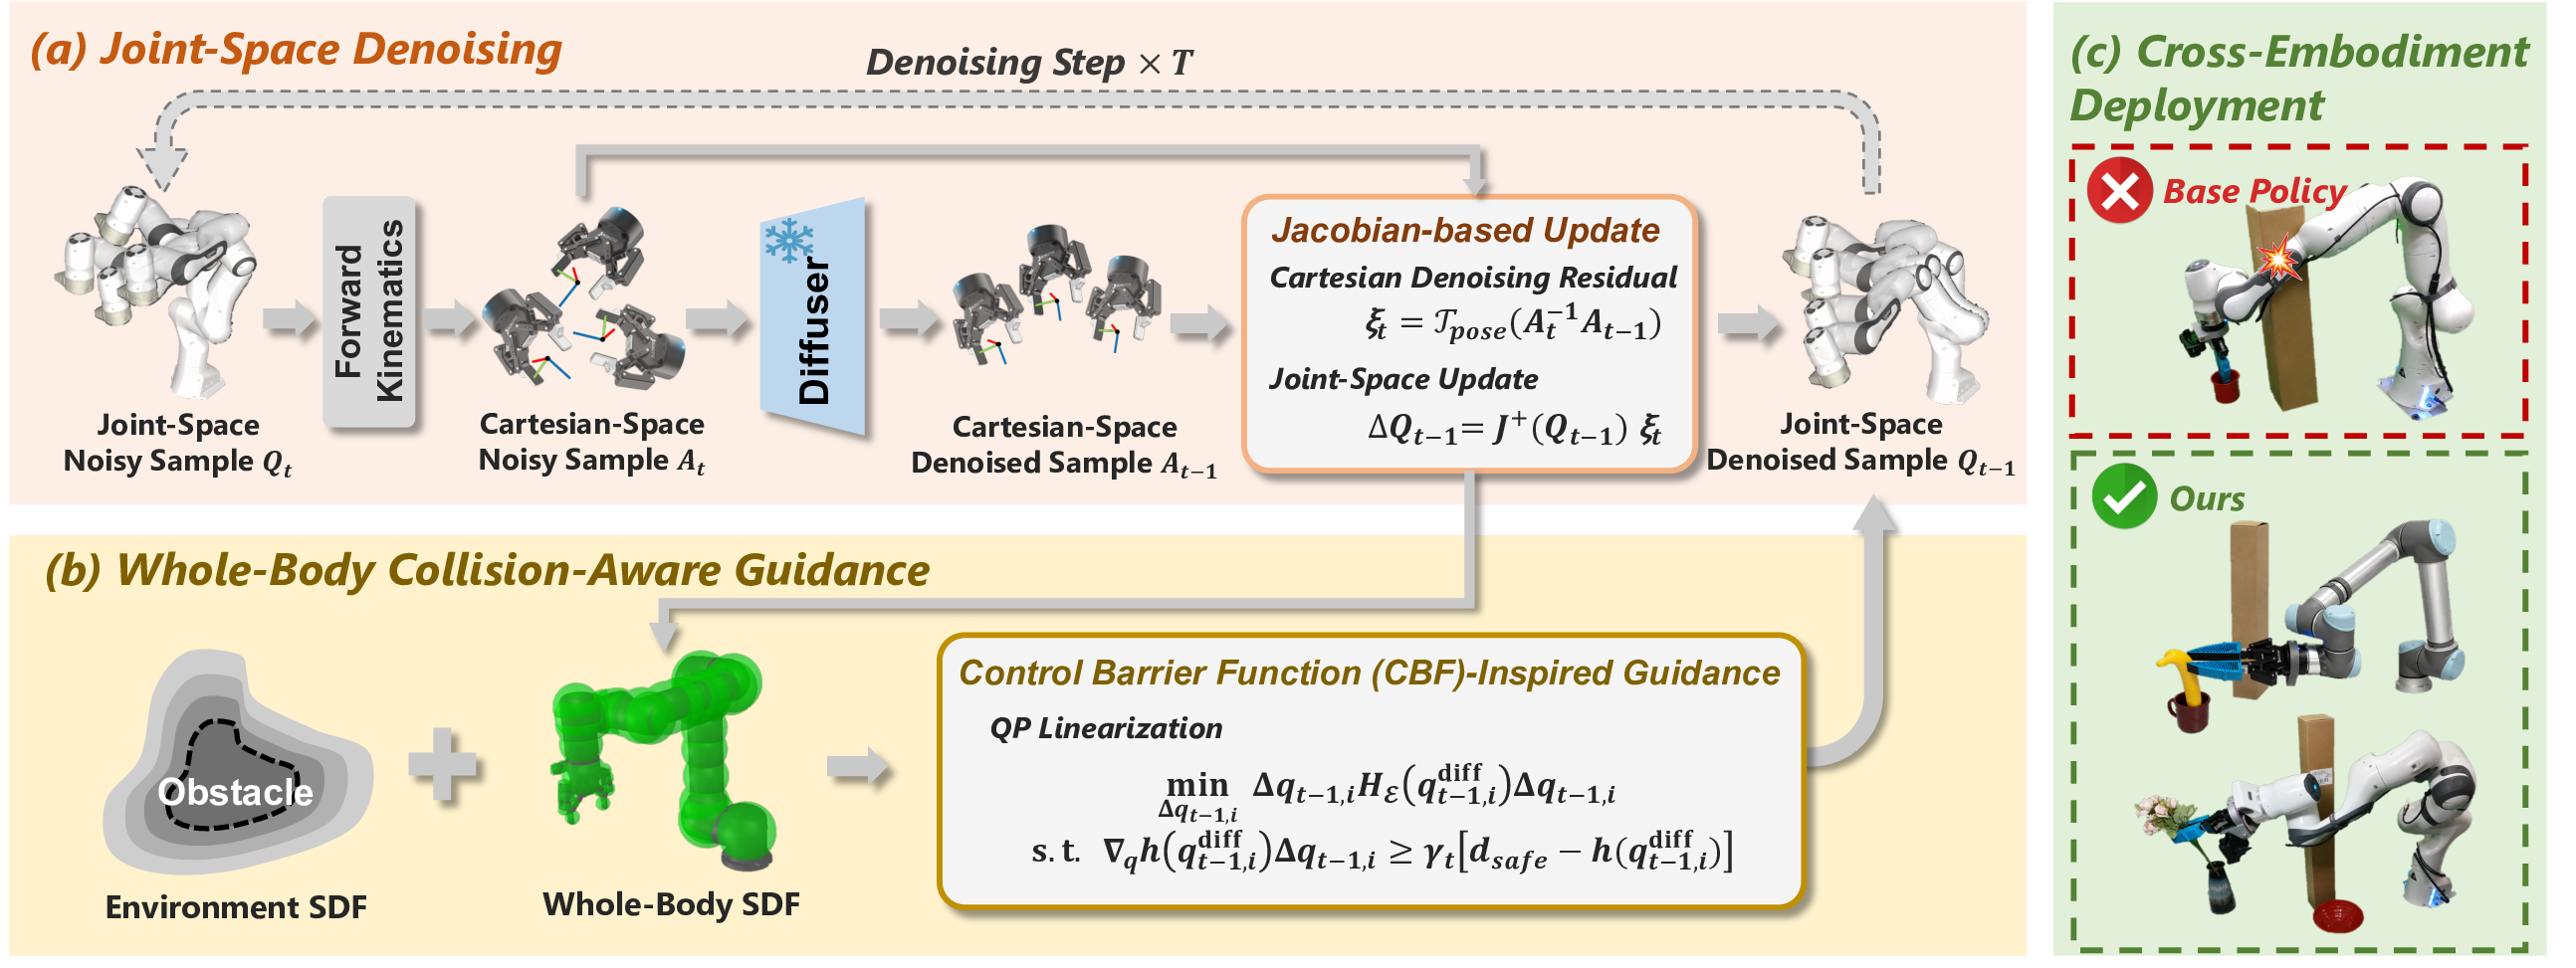
Frozen Cartesian policy
The learned denoiser remains in the embodiment-agnostic end-effector action space.
Joint-space sampling
Forward kinematics and damped Jacobian updates lift the reverse-diffusion sample into the target robot's joints.
Whole-body guidance
CBF-inspired QP guidance steers robot-body motion away from known obstacles while preserving end-effector behavior.
Citation
BibTeX
@inproceedings{wang2026embodisteer,
  title={EmbodiSteer: Steering Embodiment-Agnostic Visuomotor Policies with Joint-Space Guidance for Zero-Shot Cross-Embodiment Deployment},
  author={Shihefeng Wang and Kangchen Lv and Mingrui Yu and Xiang Li},
  booktitle={10th Annual Conference on Robot Learning},
  year={2026},
  url={https://openreview.net/forum?id=2Z8xQxrlsY}
}